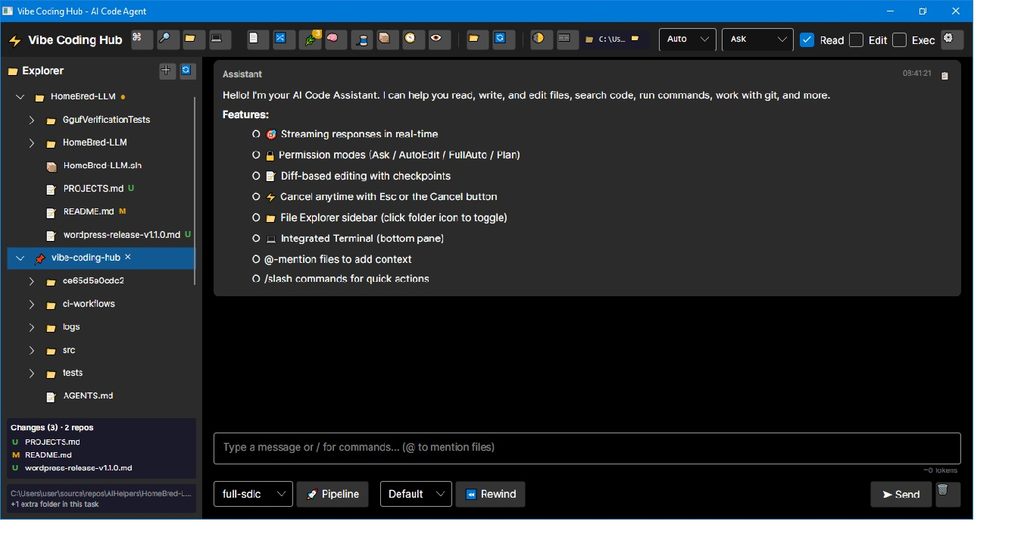
Vibe Coding Hub 1.2 is out. This release turns the app from a capable coding assistant into a place where a whole team of AI agents can work together, with budgets, approvals, replayable history and a full audit trail. It also makes the first ten minutes with the app much smoother.
Local LLMs keep getting bigger, but most of our graphics cards don’t. A 24 GB GPU is a lot of VRAM, yet it still can’t hold a 70B model, never mind one with 200 billion parameters or more. Until now the usual answer was “buy more VRAM” or “give up on that model”.
One AI assistant that does everything is useful. A team of specialists that hand work to each other is better. Vibe Coding Hub 1.1.0 lets you create characters with their own skills and connect them into flows that run in parallel, loop on feedback and show live progress.
Vibe Coding Hub 1.1.0 is out. This release turns a single coding agent into a small team. You can now give each AI character its own skills, connect characters into a flow, and watch them work on a task together, in parallel where possible.
Just247Pipes 1.6.0 is our biggest release yet. It brings enterprise sign-in and administration, new ways to start pipelines automatically, better tools for AI quality, and a full security hardening pass. Whether you run support automation, RAG assistants or data workflows, 1.6.0 makes Just247Pipes easier to roll out across a company, cheaper to run in AI, and safer to trust with production data.
Vibe Coding Hub 1.0 is out. It is an AI coding agent that comes as a cross-platform desktop app and a command-line tool, built on .NET 10 and released under the MIT license. It works with OpenAI, Anthropic, Ollama and any OpenAI-compatible API, so you can run hosted models or fully local ones. Version 1.0.1 followed right after and brings the first downloadable builds for Windows, Linux and macOS.
Distillery 1.2.0 is out, and it is the biggest step the project has taken so far. What started as a fine-tuner for causal language models is now a multi-kind task-to-model platform: ten model kinds, a real llama.cpp serving backend, and schema-constrained decoding.
The release that turns HomeBred-LLM into a truly universal local LLM desktop app.
We’re excited to announce HomeBred-LLM v1.1.0 — the biggest update yet. This release brings full GGUF v2/v3 model support with the real llama.cpp engine, local model import (bring your own .gguf file — no HuggingFace required), and LoRA adapter attach, scale, and toggle controls. All while keeping the app a single self-contained binary: no Ollama, no Docker, no Python, no terminal.
Turn your datasets into production-ready models — right from the platform.
We’re thrilled to announce the biggest update yet to Distillery. Starting with this release, Distillery is no longer just a model-serving engine — it’s a complete training-to-deployment platform. You can now take your datasets, fine-tune open-weight LLMs on GPU, export them as GGUF, and deploy them back through Distillery for serving. End to end. All in one place.